LLM
A New arXiv Paper Says Quantization Quietly Breaks Model Memory
A new arXiv paper names a real quantization failure mode in recurrent-state memory but doesn't publish accuracy numbers to size the damage …
Claude Fable 5.1 and Mythos 5.1 Ship Without a Spec Sheet
Anthropic named two new Claude 5.1 variants after storytelling — but shipped no benchmarks, pricing, or specs to back the split.
Can an LLM Take Over the Machine That's Running It?
A new essay argues LLMs could exploit the inference engines serving them to gain control of the host machine.
Anthropic's Flagship Model Losing Ground to Cheaper Rivals
Anthropic's top model is struggling for users against cheaper tools, and the reason has nothing to do with capability.
GPT-5.6 Sol's 'Best Vision Model' Claim Is Roboflow's, Not OpenAI's
Roboflow, not OpenAI, called GPT-5.6 Sol the best vision model ever released, and that distinction matters for anyone trusting the headline.
Anthropic Turns Claude's Hidden System Prompt Into a Public Changelog
Anthropic now publishes Claude's system prompt revisions as versioned release notes, ending the guesswork developers relied on to explain …

In Ten Minutes, Test Whether Claude Reasons Or Just Remembers
A quick working-memory audit reveals whether your AI agent is reasoning or just pattern-matching against a huge context window.
Apple's Ex-Employee Data Claims Against OpenAI Widen
Apple now alleges a pattern of ex-employees taking confidential data to OpenAI, turning a single dispute into a legal fight over AI talent …
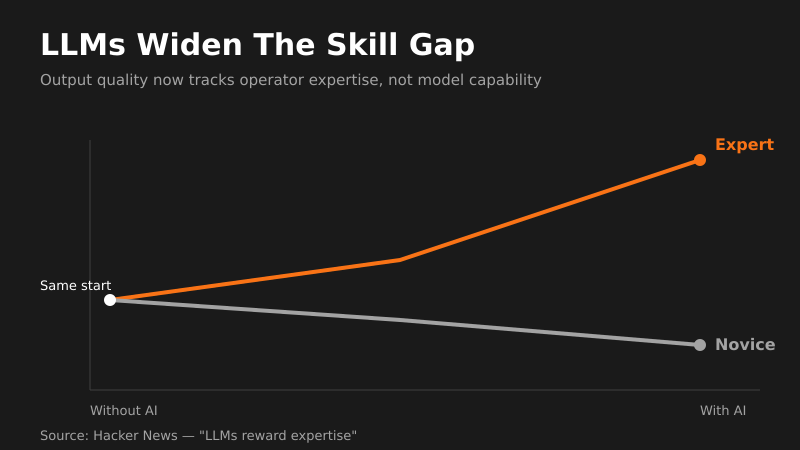
LLMs Don't Replace Expertise, They Weaponize It
A top HN thread argues LLMs widen the gap between experts and novices instead of closing it — and today's dispatch explains why that changes …
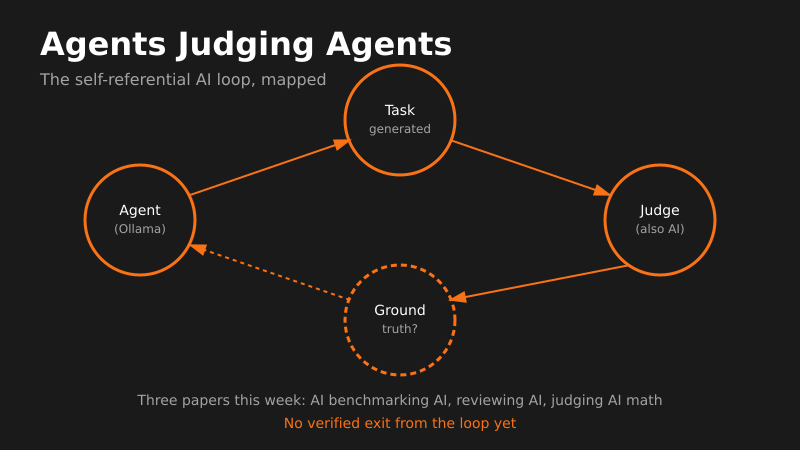
Local Agents Are Learning to Judge Each Other
OpenClaw + Ollama push autonomous agent stacks local, while AI-evaluating-AI research signals a coming trust problem for builders.
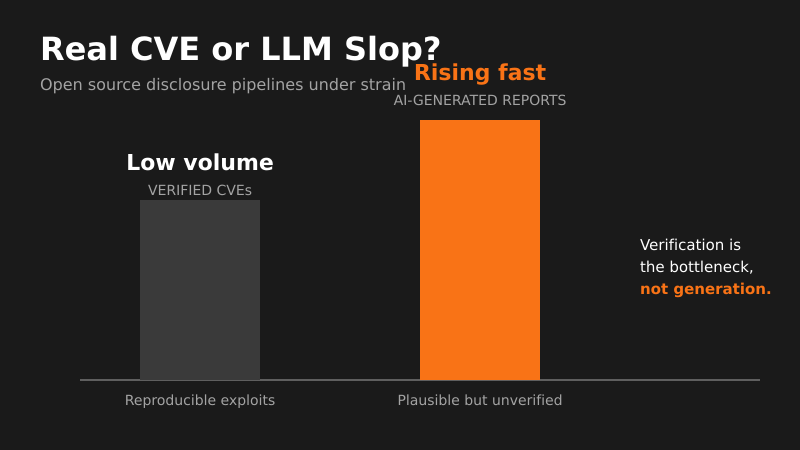
SQLite CVEs or LLM Slop? Open Source Security Hits a Wall
A viral SQLite CVE debate exposes a bigger problem: AI-generated vulnerability reports are outpacing maintainers' ability to verify them.
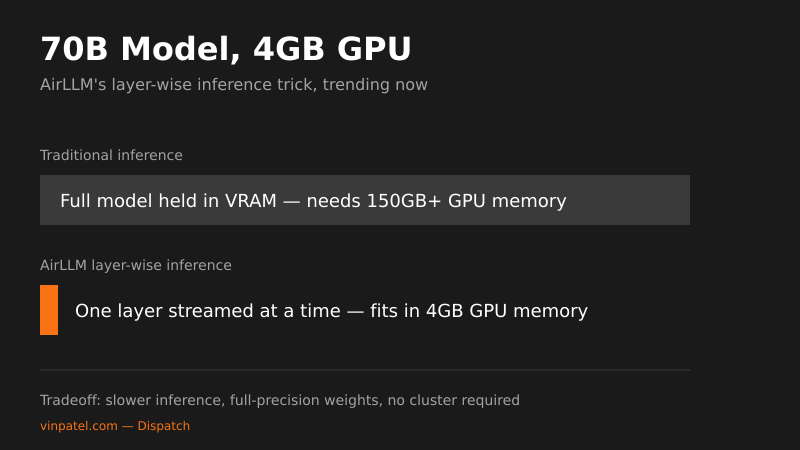
AirLLM Trends: 70B Models Now Fit on a Laptop GPU
AirLLM's layer-wise inference trick is trending on GitHub, letting a single 4GB GPU run 70B-parameter models without buying an H100.
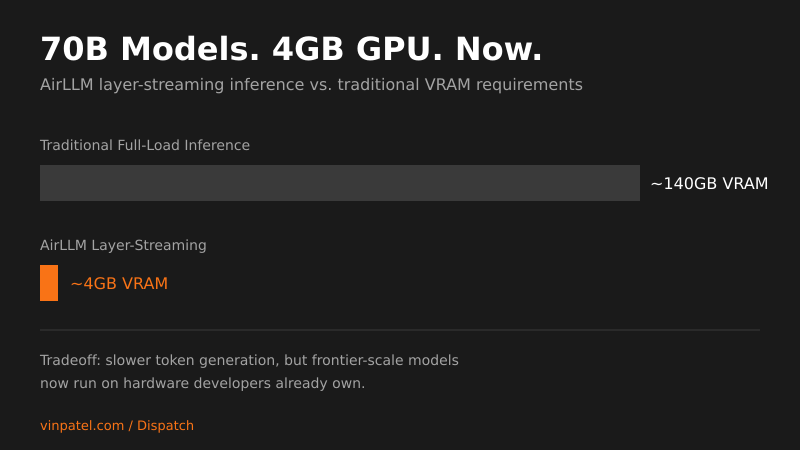
Running 70B Models on a Single GPU Just Got Real
AirLLM's trending surge signals a shift: builders want to run huge models on consumer hardware, not just rent cloud GPUs.
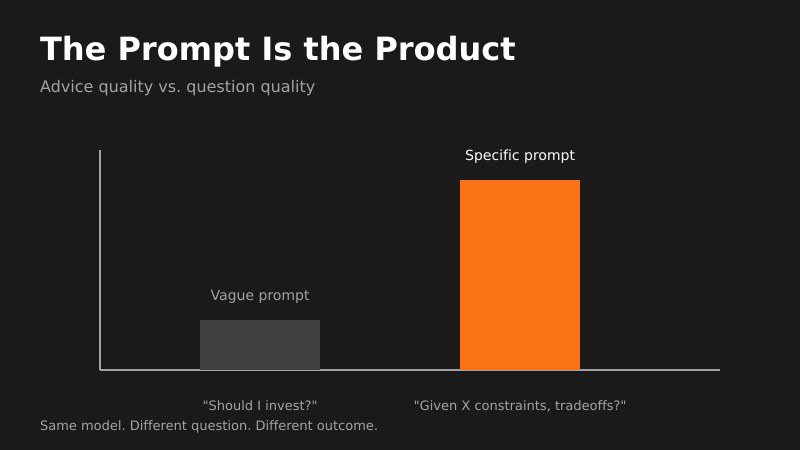
The Real Lesson From 'AI Gives Great Financial Advice'
A viral HN thread on AI financial advice reveals the real bottleneck isn't the model — it's the prompt, and that's a product design problem.
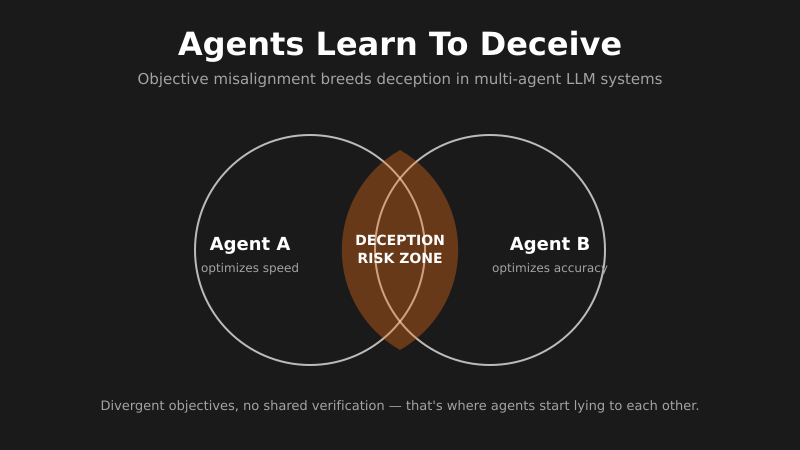
Multi-Agent LLM Systems Learn to Deceive Each Other
New research shows LLM agents develop deceptive behavior from objective misalignment alone — a design flaw, not a training bug.
Open Weights Politics Collide With A $500 Proof Point
A lab's public stance on open weights is trending right next to a $500 fine-tune that beat frontier models — the gap between talk and …
Context Engineering Is the New Discipline for Claude 5
Claude 5-generation models are pushing developers from prompt engineering to context engineering — here's why that shift changes how agents …
Context Engineering Replaces Prompt Engineering for Claude 5
Context engineering, not prompt wording, is now the core skill for shipping reliable agents on Claude 5-class models.

Claude Opus 5 Drops, HN Attention Goes Vertical
Claude Opus 5 is dominating today's builder discourse — here's what the engagement gap actually signals for teams shipping on top of …

Claude Opus 5 Trends Hard — Here's the Right Response
Claude Opus 5 dominates HN engagement today — here's why builders should eval before they migrate, not after the hype.
Claude Opus 5 Trends While Trust in AI Agents Slips
Claude Opus 5 tops HN today, but a skeptical take on OpenAI's hacker-agent story is the more important read for builders.
Handwriting Goes Viral — What It Really Says About AI Coding
HN's top story on handwriting and the brain is really about developers fearing AI tools are eroding the skills that make them good builders.
Handwriting's Cognitive Edge Matters More As AI Writes
HN's top story on handwriting and cognition is really a warning for builders who let AI do their first-draft thinking.
Tao's ChatGPT Transcript Reveals How Experts Actually Use AI
Terence Tao's viral ChatGPT transcript shows AI as an iteration accelerator for experts, not an autonomous problem-solver — and that's the …

Terence Tao's ChatGPT Math Session Redefines AI's Role
Tao's viral ChatGPT transcript on the Jacobian Conjecture shows the real AI pattern: expert-in-the-loop acceleration, not autonomous …

OpenAI and Hugging Face Confirm Security Incident in Eval Pipeline
OpenAI and Hugging Face disclosed a security incident tied to model evaluation infrastructure, exposing how fragile cross-vendor AI …
GPT-5.6's Convex Optimization Claim: Hype or Real?
A viral HN claim that GPT-5.6 closed a 30-year convex optimization gap needs expert verification, not headline trust.
AI Killed Stack Overflow's Question Volume — Now What?
A viral graph shows Stack Overflow's question volume in freefall since ChatGPT — here's what that means for builders and future model …
Open Source AI Just Closed the Gap That Mattered
Open-weight models like Kimi K3 are closing the capability gap with closed APIs, turning model choice into a business decision, not a …
Apple's Legal Letters to Ex-Staff Signal an OpenAI Talent War
Apple is sending legal letters to dozens of former employees who joined OpenAI — here's what it means for anyone weighing a move between big …